iFANN
    Buscar no iFANN...
    Entrar
    Início
    Notícias
    Vídeos
    Fotos
    GIFs
    Explorar
    Enquetes
    Prêmios
    iFAMOUS
    Wiki
    Anime
    Salas
    Notificações
    Mensagens
    Salvos
    Perfil
    WikiPrêmiosiFAMOUSRankingsSetoresRecompensas para criadoresRecompensas para usuáriosTermosPrivacidadeDiretrizes da comunidadeRemoção / DMCAAjudaDesenvolvedores

    © 2026 iFANN

    Início
    Buscar
    Mensagens
    Alertas
    Perfil
    Foto
    Nate
    Nate@nate_5122h
    💭Tech💭AI
    EdgeRock-4B from Rock Matrix

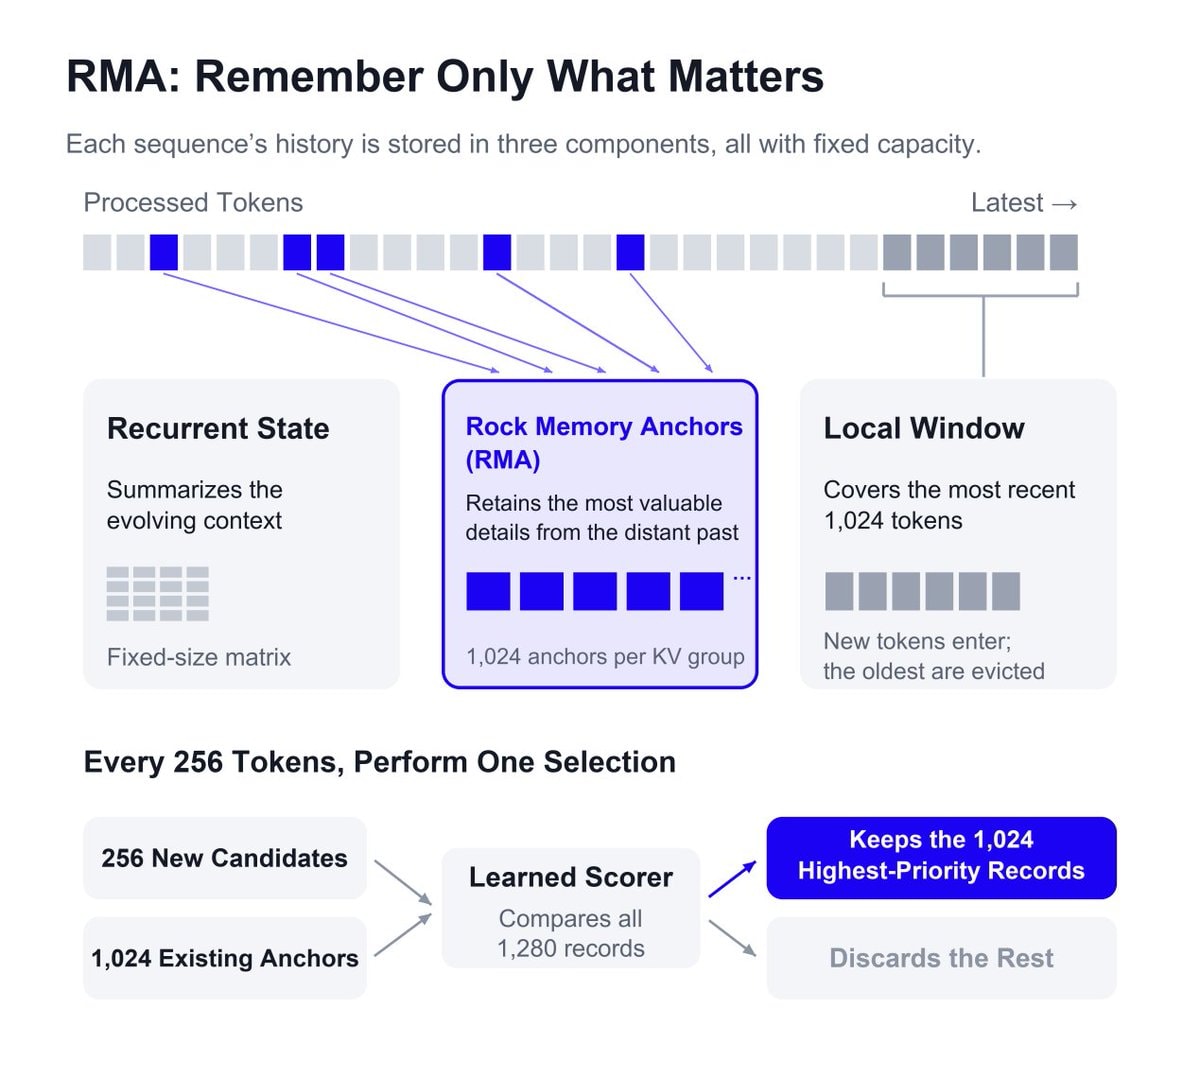
    @nate_512Istg the part that actually gets me about EdgeRock-4B is that Rock Matrix kept the KV cache flat. 72 MiB per sequence, and it does not care whether you are sitting at a short prompt or pushing all the way out to 256K tokens. That is the whole trick, and the open-source 4B model pulls it off by fusing recurrent state with local attention and Rock Memory Anchors (RMA). Learned KV records get parked in a fixed-capacity bank, so the system can still dig up info from way earlier in the context even after it has fallen out of the local attention window. Normal LLMs just keep stacking cache as the context grows, which is exactly the wall this thing sidesteps. Now the numbers, because they are cooked in the best way. Output throughput lands at 12,124 tokens per second on a single 80GB Hopper GPU with 512 concurrent sequences running. Compare that to Qwen3.5-4B and you are looking at 6.42 times the output. Cache usage drops 99.1% at 256K context versus the traditional growth approach. Long generation holds 233.7 tokens per second even when the model chews through 128K of input and then writes another 128K of output. And it still reasons. 82.9% mean pass@1 on AIME 2024, 2026. The strongest bounded-state baseline they evaluated only hit 18.8%. Long context, a cache that never balloons, and reasoning that keeps up, all from an open-source 4B model

    Ver publicação original
    EdgeRock-4B from Rock Matrix

    Foto de @nate_512· Oct 30, 2026· Tech

    Sobre esta foto

    This is a diagram explaining a concept called RMA: Remember Only What Matters. It shows how sequence history is stored in three components: Recurrent State, Rock Memory Anchors (RMA), and Local Window. The diagram uses blue and gray squares to represent tokens and arrows to illustrate data flow. The overall mood is informative and technical, with a clean, minimalist style. A notable detail is the clear breakdown of how new tokens are processed and older ones are evicted. ON-SCREEN TEXT: RMA: Remember Only What Matters, Recurrent State, Rock Memory Anchors (RMA), Local Window, Latest →, Every 256 Tokens, Perform One Selection, 256 New Candidates, 1,024 Existing Anchors, Learned Scorer, Compares all 1,280 records, Keeps the 1,024 Highest-Priority Records, Discards the Rest.

    Ver todas as fotos de Tech

    ?

    Mais fotos de Tech

    Ver todas as fotos de Tech
    AGIBOT Worken robot productivity frameworkAGIBOT Worken robot productivity frameworkIntel stock crash2Intel stock crashElon Musk on 2028 DemocratsElon Musk on 2028 DemocratsCar break-in with shattered windowCar break-in with shattered windowOpen Ontologies GitHub releaseOpen Ontologies GitHub releaseRed Baron Employee of the MonthRed Baron Employee of the MonthReddit login requirement announcedReddit login requirement announcedBitcoin price crash below $78,5004Bitcoin price crash below $78,500Intel stock crash Q3 20262Intel stock crash Q3 2026Geoffrey Hinton on AI consciousness2Geoffrey Hinton on AI consciousnessrobot with cow head and red cap2robot with cow head and red capCristiano Ronaldo VAR offside reviewCristiano Ronaldo VAR offside reviewTwitter X Made on X label2Twitter X Made on X labelRobyn invite-only AI agents toolRobyn invite-only AI agents toolWalt Red Baron GoFundMe passes $220,0002Walt Red Baron GoFundMe passes $220,000360 terabyte glass disc storage2360 terabyte glass disc storageLily Phillips Lily AI announcement2Lily Phillips Lily AI announcementSatya Nadella on AI security2Satya Nadella on AI security
    Foto
    Nate
    Nate@nate_5122h
    💭Tech💭AI
    EdgeRock-4B from Rock Matrix

    @nate_512Istg the part that actually gets me about EdgeRock-4B is that Rock Matrix kept the KV cache flat. 72 MiB per sequence, and it does not care whether you are sitting at a short prompt or pushing all the way out to 256K tokens. That is the whole trick, and the open-source 4B model pulls it off by fusing recurrent state with local attention and Rock Memory Anchors (RMA). Learned KV records get parked in a fixed-capacity bank, so the system can still dig up info from way earlier in the context even after it has fallen out of the local attention window. Normal LLMs just keep stacking cache as the context grows, which is exactly the wall this thing sidesteps. Now the numbers, because they are cooked in the best way. Output throughput lands at 12,124 tokens per second on a single 80GB Hopper GPU with 512 concurrent sequences running. Compare that to Qwen3.5-4B and you are looking at 6.42 times the output. Cache usage drops 99.1% at 256K context versus the traditional growth approach. Long generation holds 233.7 tokens per second even when the model chews through 128K of input and then writes another 128K of output. And it still reasons. 82.9% mean pass@1 on AIME 2024, 2026. The strongest bounded-state baseline they evaluated only hit 18.8%. Long context, a cache that never balloons, and reasoning that keeps up, all from an open-source 4B model

    Ver publicação original
    EdgeRock-4B from Rock Matrix

    Foto de @nate_512· Oct 30, 2026· Tech

    Sobre esta foto

    This is a diagram explaining a concept called RMA: Remember Only What Matters. It shows how sequence history is stored in three components: Recurrent State, Rock Memory Anchors (RMA), and Local Window. The diagram uses blue and gray squares to represent tokens and arrows to illustrate data flow. The overall mood is informative and technical, with a clean, minimalist style. A notable detail is the clear breakdown of how new tokens are processed and older ones are evicted. ON-SCREEN TEXT: RMA: Remember Only What Matters, Recurrent State, Rock Memory Anchors (RMA), Local Window, Latest →, Every 256 Tokens, Perform One Selection, 256 New Candidates, 1,024 Existing Anchors, Learned Scorer, Compares all 1,280 records, Keeps the 1,024 Highest-Priority Records, Discards the Rest.

    Ver todas as fotos de Tech

    ?

    Mais fotos de Tech

    Ver todas as fotos de Tech
    AGIBOT Worken robot productivity frameworkAGIBOT Worken robot productivity frameworkIntel stock crash2Intel stock crashElon Musk on 2028 DemocratsElon Musk on 2028 DemocratsCar break-in with shattered windowCar break-in with shattered windowOpen Ontologies GitHub releaseOpen Ontologies GitHub releaseRed Baron Employee of the MonthRed Baron Employee of the MonthReddit login requirement announcedReddit login requirement announcedBitcoin price crash below $78,5004Bitcoin price crash below $78,500Intel stock crash Q3 20262Intel stock crash Q3 2026Geoffrey Hinton on AI consciousness2Geoffrey Hinton on AI consciousnessrobot with cow head and red cap2robot with cow head and red capCristiano Ronaldo VAR offside reviewCristiano Ronaldo VAR offside reviewTwitter X Made on X label2Twitter X Made on X labelRobyn invite-only AI agents toolRobyn invite-only AI agents toolWalt Red Baron GoFundMe passes $220,0002Walt Red Baron GoFundMe passes $220,000360 terabyte glass disc storage2360 terabyte glass disc storageLily Phillips Lily AI announcement2Lily Phillips Lily AI announcementSatya Nadella on AI security2Satya Nadella on AI security