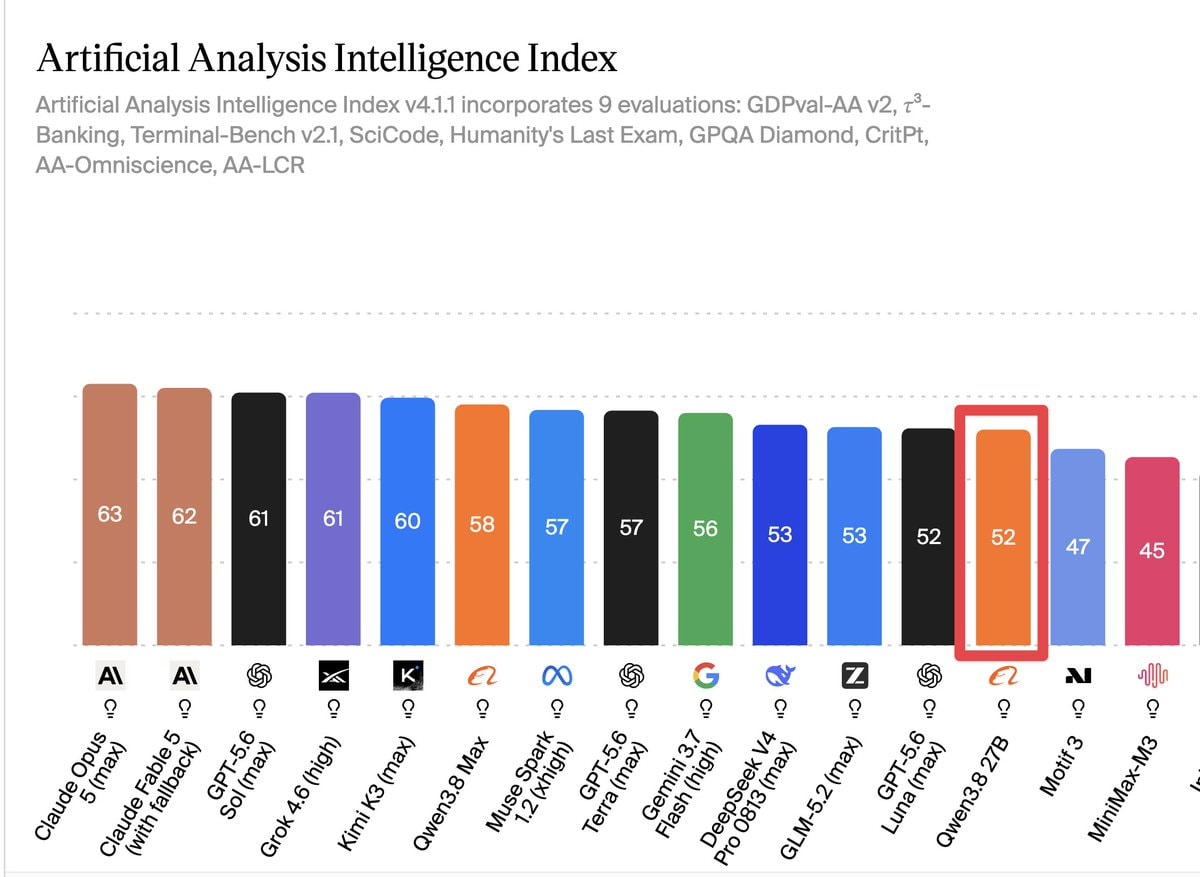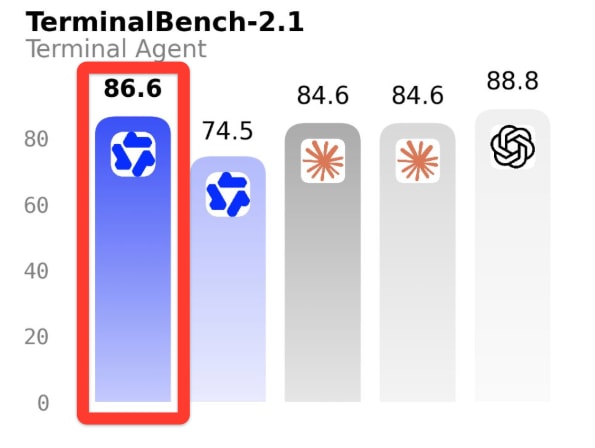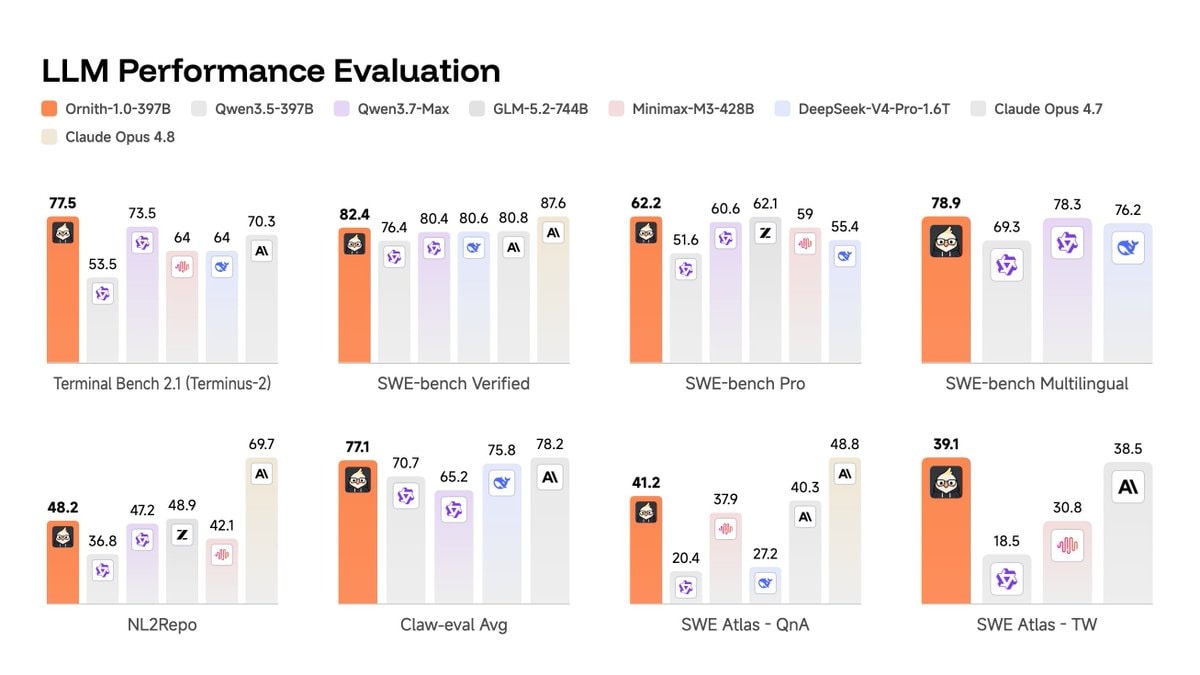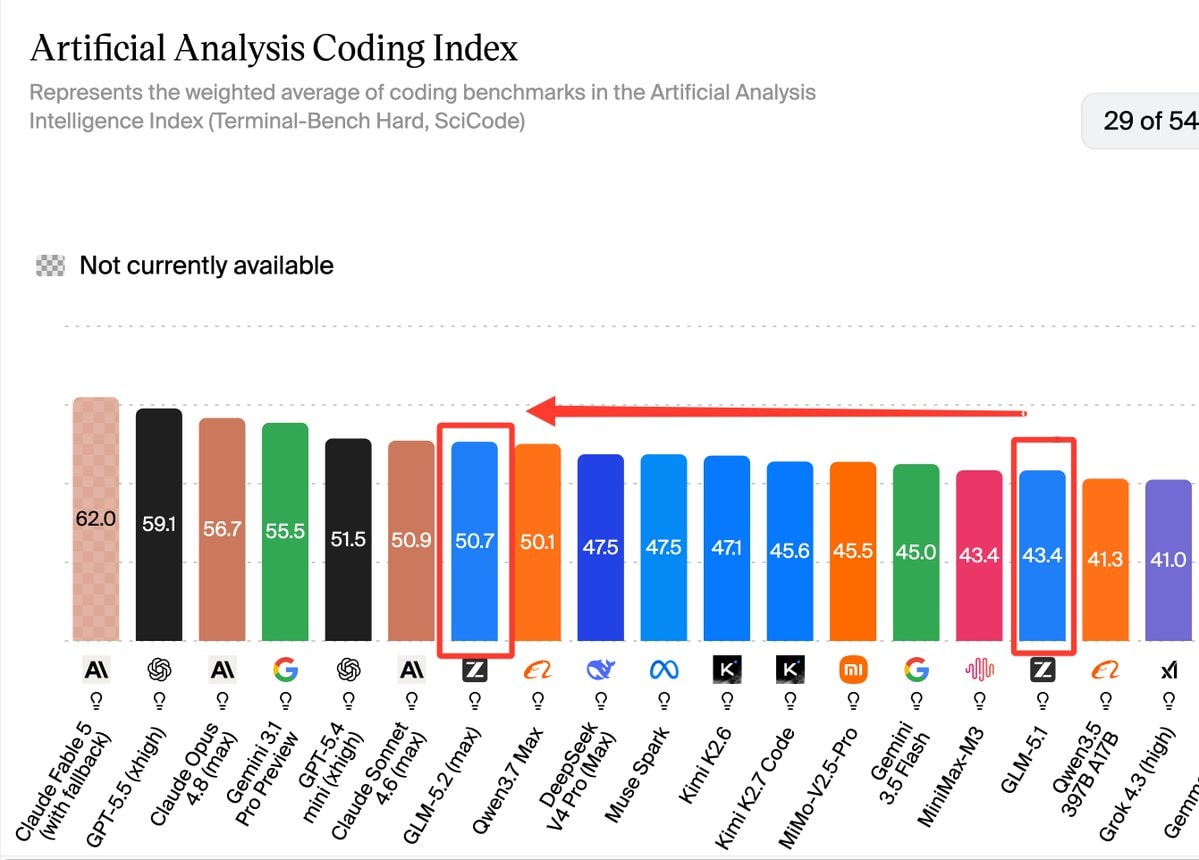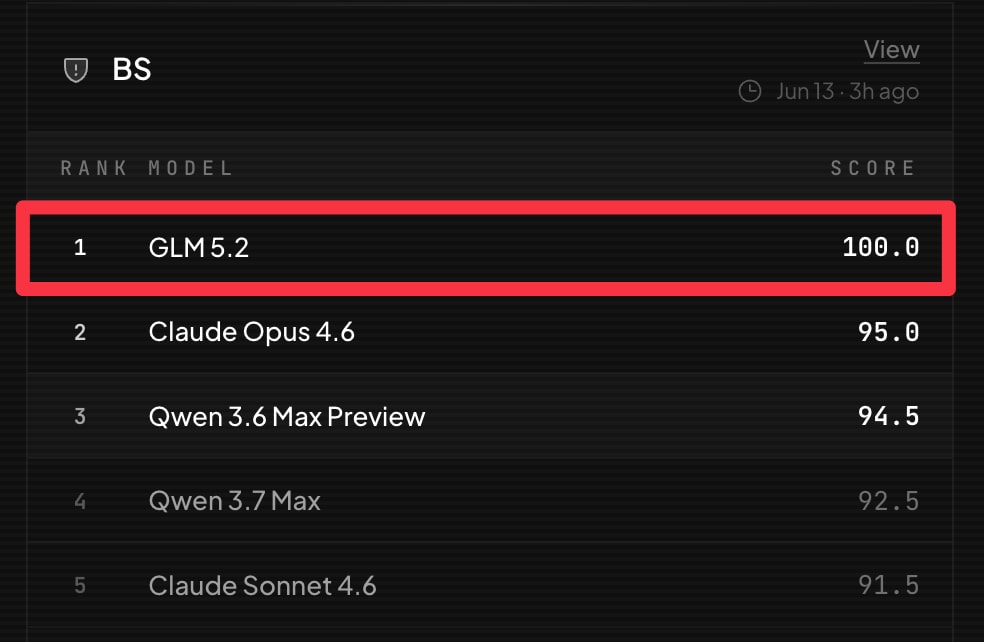
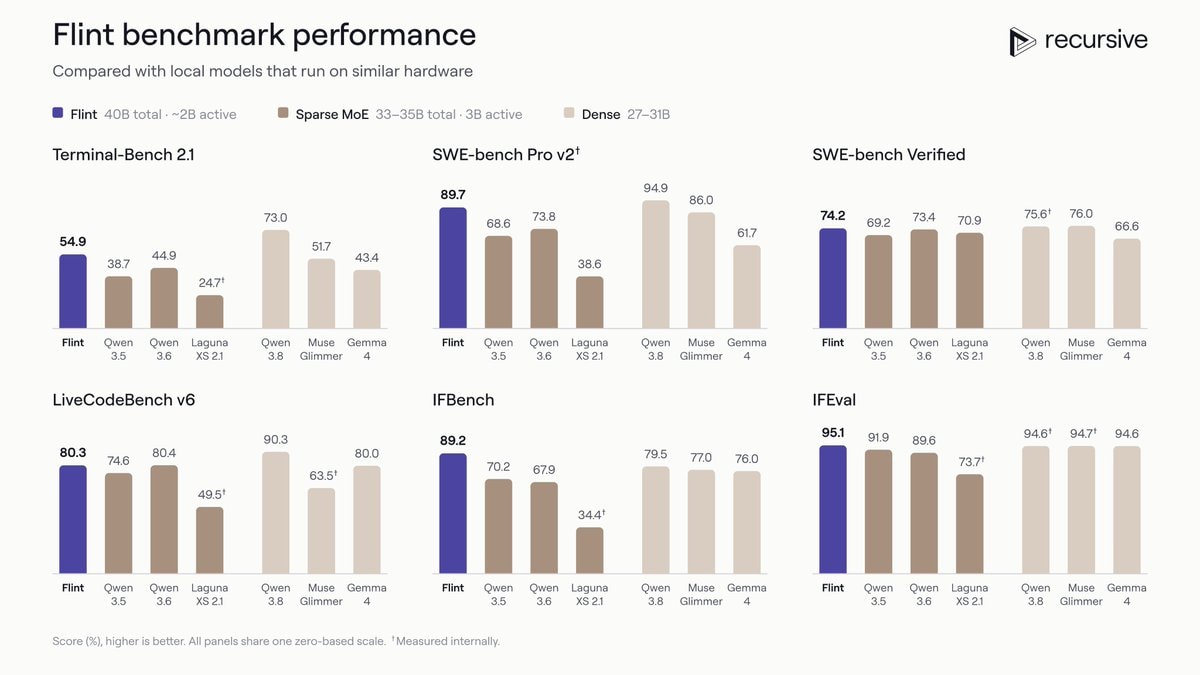
@nate_512Istg the scale of this release is barely being talked about. A US lab dropped a 40B open-weight coding model that actually tops three major benchmarks against Qwen, Muse, and Gemma. You get over 125 tokens per second on a MacBook or 150+ on RTX Spark hardware without any per-token fees or usage limits. Your personal laptop is finally the real endpoint for this tech.
Ver publicação original